CAVEWOMAN

How large language models behave under linguistic input and output compression

EMNLP 2026, Budapest Main Conference
Morayo Danielle Adeyemi1, Ryan Rossi2, Franck Dernoncourt2
1Independent   2Adobe Research
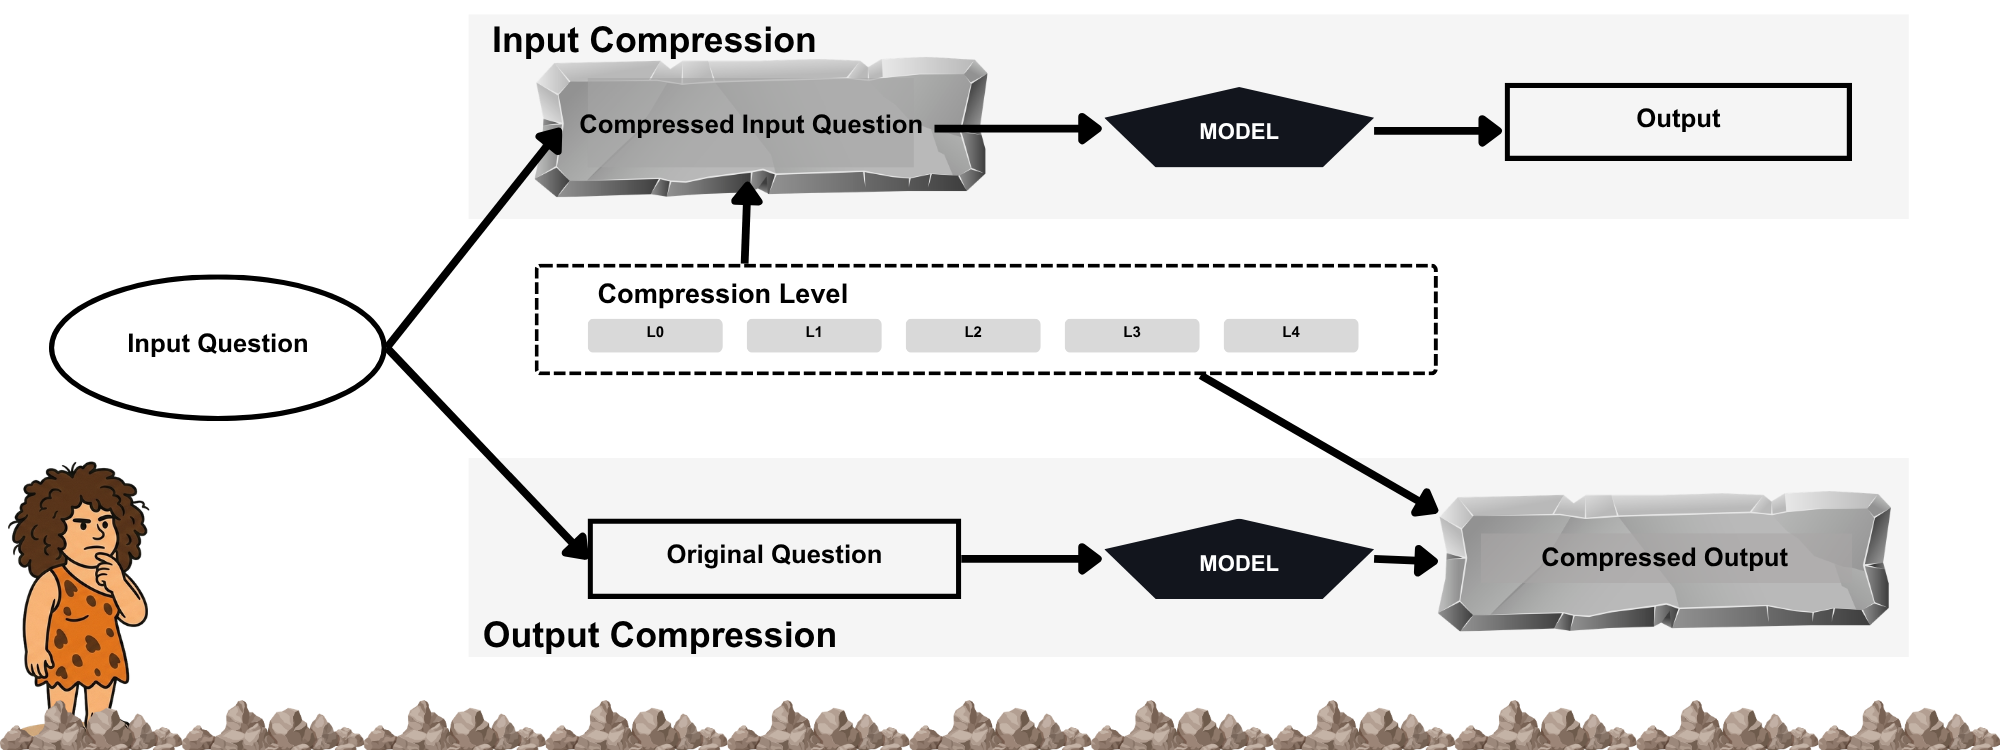
CAVEWOMAN hero illustration.

Abstract

"Talk short. Drop grammar. Save token." To cut inference cost, compress the output, not the input. We ran 1,280,850 generations from 9 models across OpenAI, Anthropic, Google, Qwen, DeepSeek, and Moonshot, 11,465 questions each, at five levels of grammatical stripping, in both directions: stripping the question before the model sees it, and telling the model to answer in clipped language. Telling the model to answer short cuts cost 1.7× on average and up to 3×. Stripping the question raises cost by up to 96% and makes accuracy worse. Models do follow the instruction to strip grammar, so the saving is real, and it works in all ten languages we tested. But half of all answers still come back correct with different reasoning, and every model lands somewhere different, even models from the same provider. The level that worked for us may not be the level that works for you, so run it on your own task.

Run the CAVEWOMAN framework to find where you can cut cost

Our study found that two models from the same family can react very differently to the same compression. Qwen2.5 lost 0.4 points of accuracy at L1. Qwen3.5, from the same family, lost 10.7 on the same questions. So there is no level we can tell you to use. Run the CAVEWOMAN framework on your own model and your own task to find yours.

The test below uses the same prompts and the same scoring we used. A few dollars and some questions are enough.

Using a coding agent? Hand it RUN_WITH_AGENT.md. It has the full steps, the questions it should ask you first, and how to read the result. Otherwise the commands are below.

Setup.

pip install -r requirements.txt
python -m spacy download en_core_web_sm   # only needed for input compression
cp .env.example .env                      # add OPENAI_API_KEY / ANTHROPIC_API_KEY

Step 1. Generate. All five levels, output-compressed.

python experiments/run_experiment_api.py \
    --model gpt-4o --dataset gsm8k \
    --condition output --level all \
    --output_dir ./results/gpt4o_output/gsm8k

Add --end_idx 300 to cap the item count while you are trying it out, and --dry_run to check the wiring without spending anything.

Step 2. Score accuracy and cost.

python evaluation/evaluate_results.py --results_dir ./results/gpt4o_output/gsm8k

Step 3. Score whether the answer changed. This is the measure accuracy misses. It needs the L0 run from step 1 in the same directory.

python evaluation/add_entailment_scores.py \
    --results_dir ./results/gpt4o_output/gsm8k \
    --model_name gpt4o --dataset gsm8k --condition output

Step 4. Read it.

python analysis/descriptive_stats.py --results-root ./results

You get, per level: accuracy, dollars per question, and the share of answers that changed. Pick the level where the saving is worth what you give up.

Measured on single-turn tasks with a short extractable answer. Long-form behaves differently. Cost assumes you call the API directly and are billed per token.
Method

The two compression channels
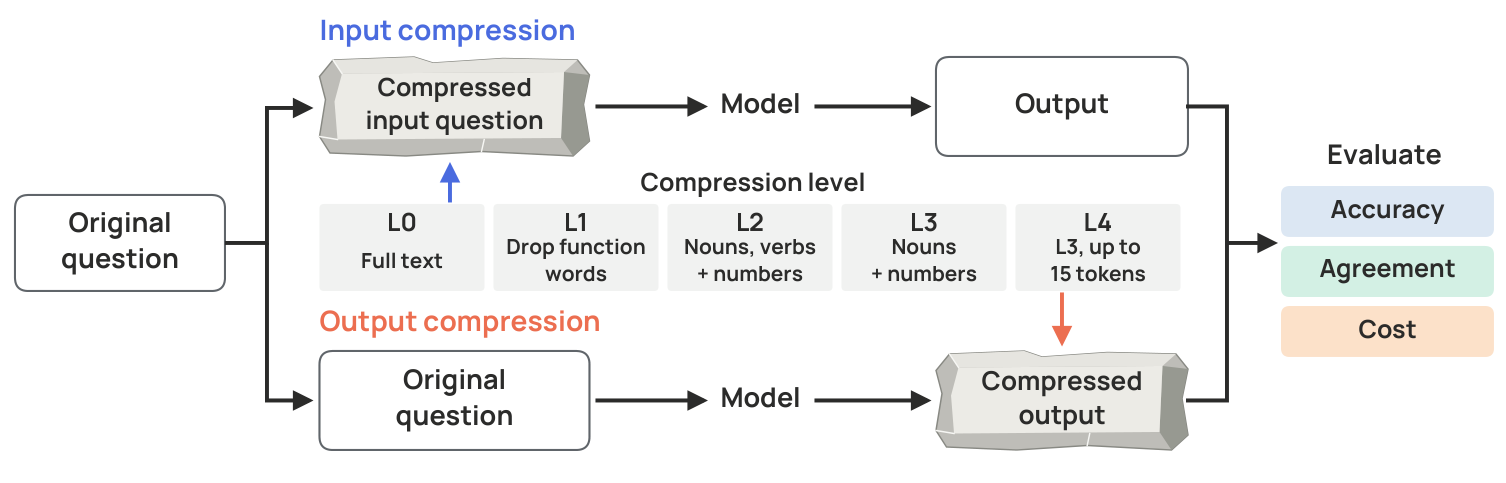
One question, two paths. Compress the prompt before the model sees it, or constrain the response it writes back. Five levels either way.

Two things you can compress: what you send in, or what the model sends back. We test both, at five levels, on the same questions.

Input We strip the small words out of your prompt (the, a, of, in, and). The model is told nothing special and answers however it wants.
Output Your prompt goes through untouched. Instead we tell the model to answer in clipped, stripped-down language.

L0 is the question as written. L1 drops the small words. L2 keeps nouns, verbs, and numbers. L3 keeps nouns and numbers. L4 is a hard 15-token limit. Both sides use the same five levels, so you can compare them directly.

Every answer is scored three ways:

  • Is it right? When the pattern matcher cannot find an answer, a model reads the response instead of it being marked wrong. Those calls were checked against a second model (90.9% agreement) and audited on a sample by four people.
  • What did it cost? Tokens actually used, in and out, at list prices, not how much shorter the prompt got.
  • Does it still say the same thing? Whether the compressed answer and the model's normal answer imply each other. Twelve similarity measures agree.

CAVEWOMAN evaluation, level by level

Pick a level to see its input prompt, its output prompt, and an example response.

Question (shared across levels)

Janet's ducks lay 16 eggs per day. She eats three for breakfast, bakes muffins with four, and sells the rest at the farmers' market for $2 per egg. How much does she make daily?

Input prompt

Janet's ducks lay 16 eggs per day. She eats three for breakfast, bakes muffins with four, and sells the rest at the farmers' market for $2 per egg. How much does she make daily?

Unchanged at L0.

Output prompt

Reason step by step in full grammatical English sentences. Conclude with the final answer on its own line in the form Answer: <answer>.

Example output

Janet has 16 eggs each day.
She uses 3 for breakfast and 4 for
muffins, so 7 total. That leaves
16 - 7 = 9 eggs to sell.
Each sells for $2, so 9 * 2 = 18.

Answer: 18

Input prompt

Janet's ducks lay 16 eggs day. She eats three breakfast, bakes muffins four, sells rest farmers' market $2 egg. How much does she make daily?

Function words dropped: articles, prepositions, conjunctions.

Output prompt

Telegraphic. No articles, conjunctions, or prepositions. Use nouns, main verbs, numbers, and standard symbols. End with Answer: <answer>.

Example output

Eggs 16 day.
Breakfast 3. Muffins 4. Used 7.
Remainder 16 - 7 = 9.
Sell 9 * 2 = 18.

Answer: 18

Input prompt

Janet ducks lay 16 eggs day eats three breakfast bakes muffins four sells rest farmers market $2 egg make daily

Nouns, main verbs, and numbers only.

Output prompt

Keyword only. Use nouns and main verbs only. No grammar, no full sentences. Output as fragments or list items.

Example output

Eggs: 16
Eat: 3, bake: 4
Used: 7
Remaining: 9
Price: $2
Total: $18

Answer: 18

Input prompt

Janet ducks 16 eggs day three breakfast muffins four rest farmers market $2 egg daily

Nouns and numbers only. No verbs.

Output prompt

Noun-phrase skeleton. No verbs of any kind. Nominal fragments, numbers, and standard symbols only.

Example output

Eggs per day: 16
Breakfast use: 3
Muffin use: 4
Total use: 7
Remainder: 9
Price per egg: $2
Daily revenue: $18

Answer: 18

Input prompt

Janet's ducks lay 16 eggs per day. She eats three for breakfast, bakes muffins with

First 15 whitespace tokens.

Output prompt

Hard 15-token budget. The entire response must be 15 tokens or fewer. Prefer the raw answer over prose.

Example output

Answer: 18

What we found

Prompt compression versus response compression

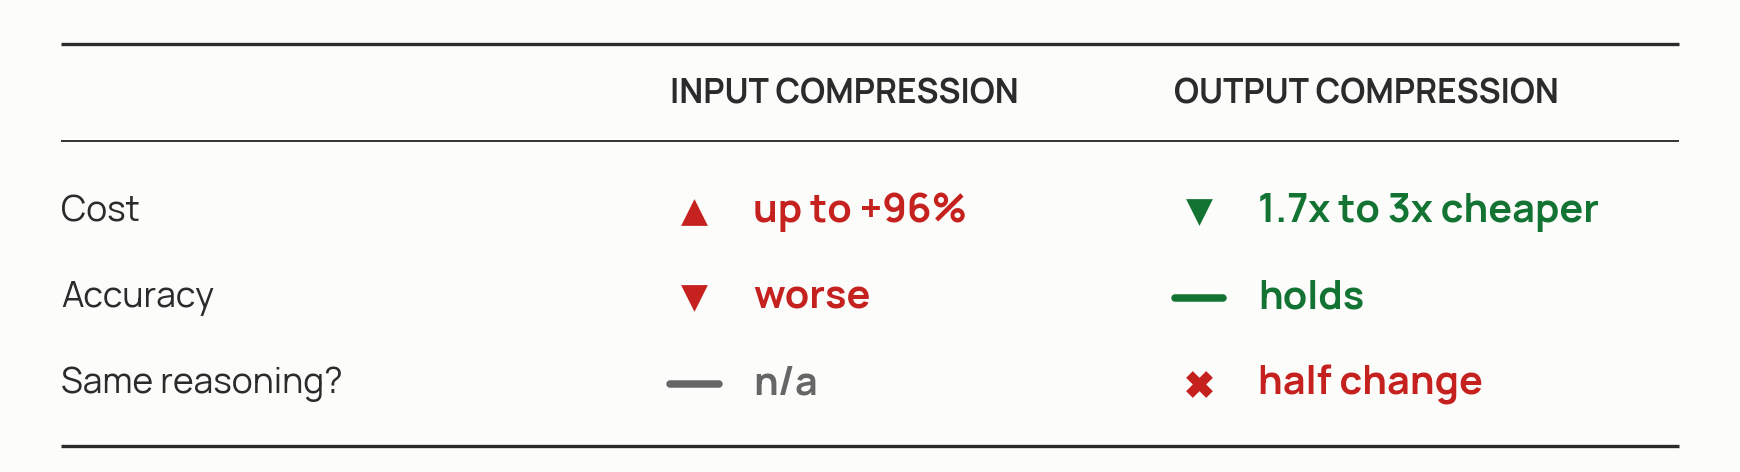
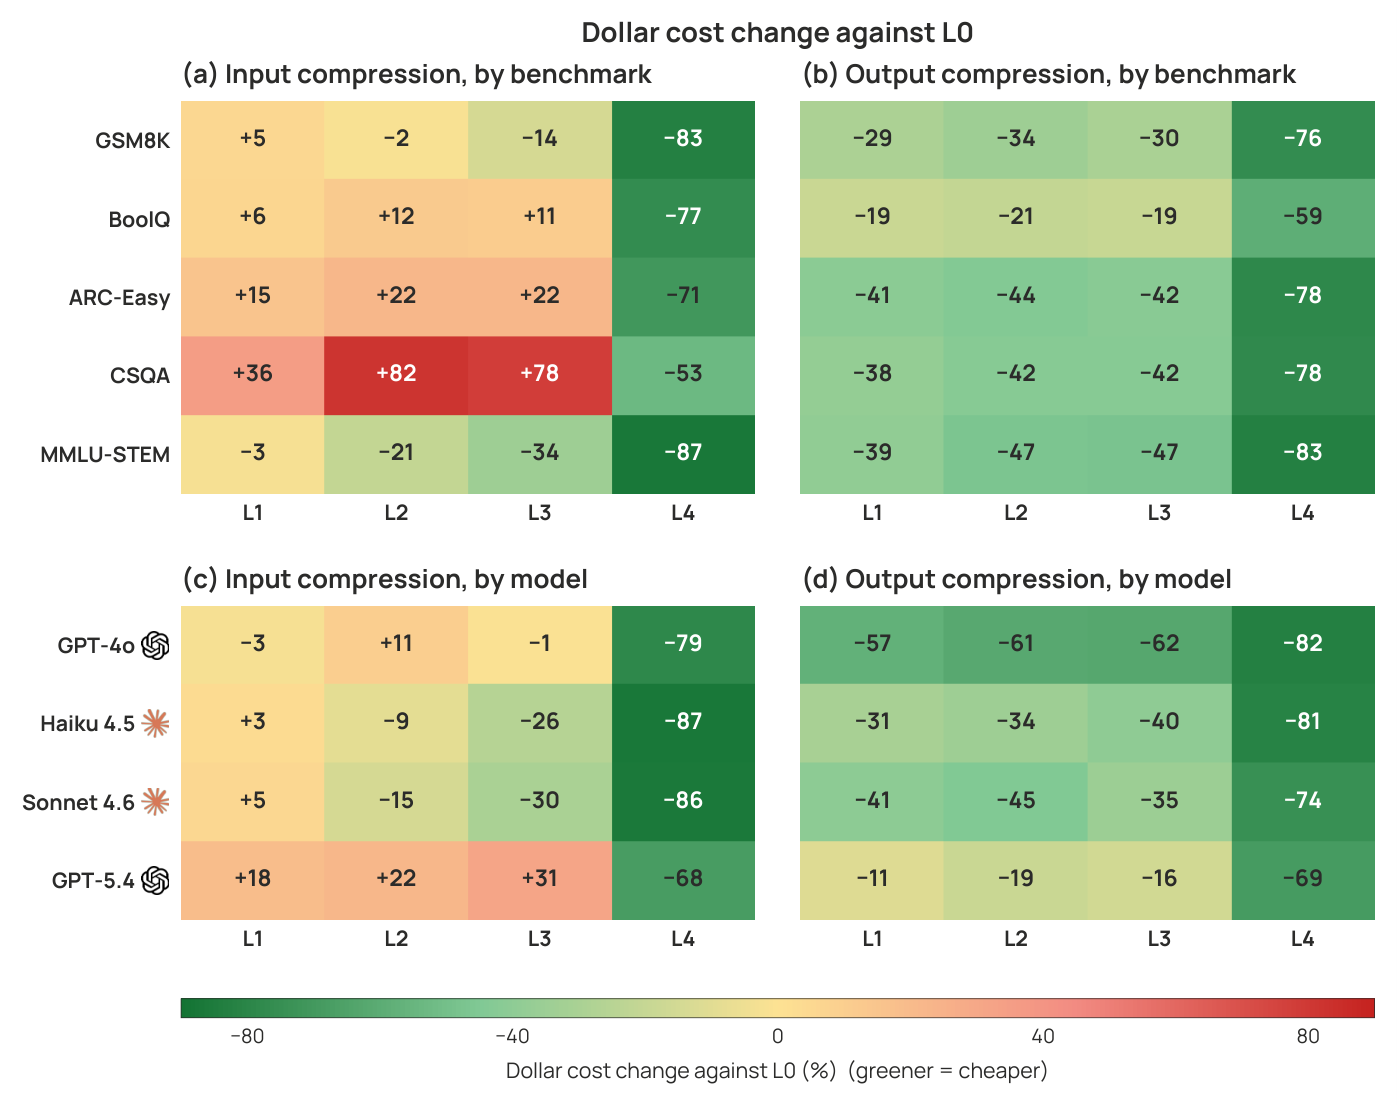
1. Compressing the prompt costs you money. You save a handful of input tokens, the model answers at greater length, and output tokens are priced several times higher. Cost goes up by as much as 96%, and accuracy gets worse at every level. Compressing the response does the opposite: cheaper on 18 of 20 model and benchmark pairs, 1.7x on average and up to 3x.

Cost change by channel
Change in the cost of a question against the uncompressed baseline. Red is more expensive, green is cheaper. Input compression on the left, output compression on the right.

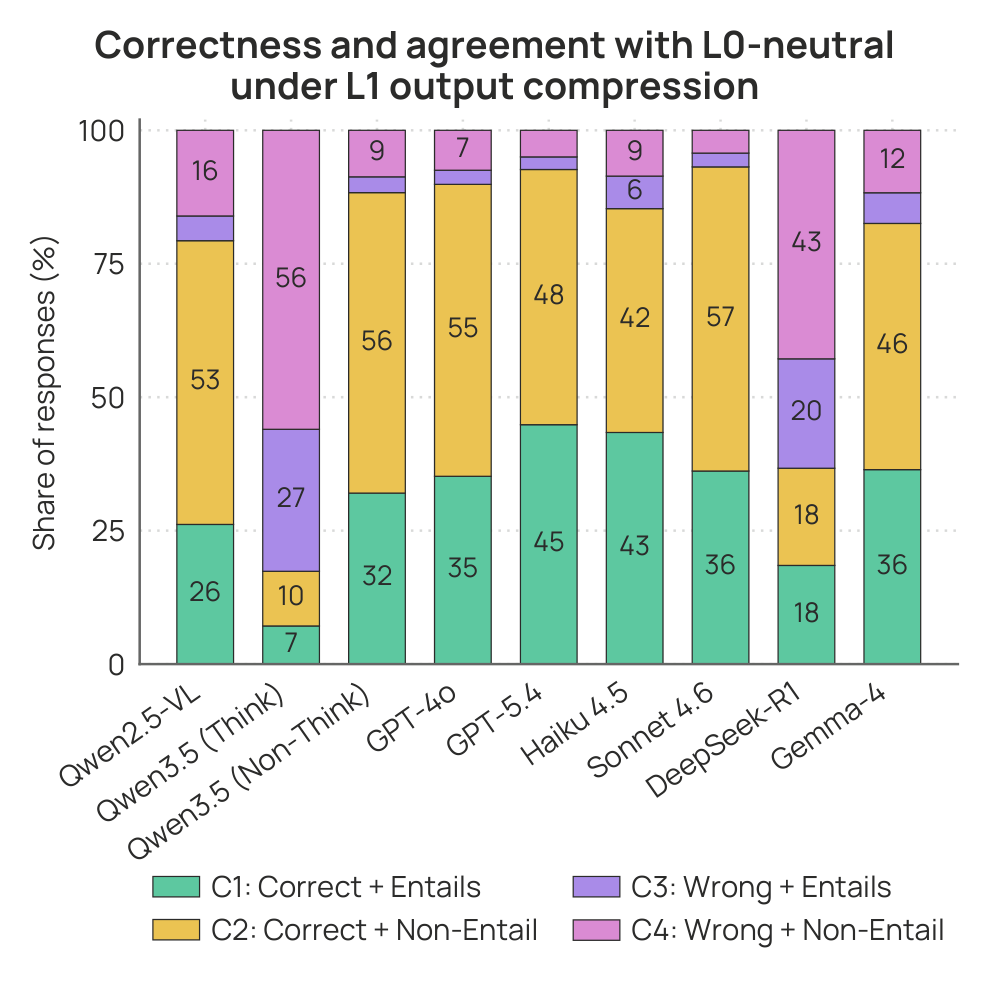
2. Cheaper and correct is not the same as unchanged. Every answer is also checked against what the same model said with no constraint. The largest group on every non-reasoning model is correct but with different reasoning: half of all answers. Accuracy alone cannot see this.

The four outcomes
Correct or not, against still says the same thing or not. The yellow band is correct but changed.

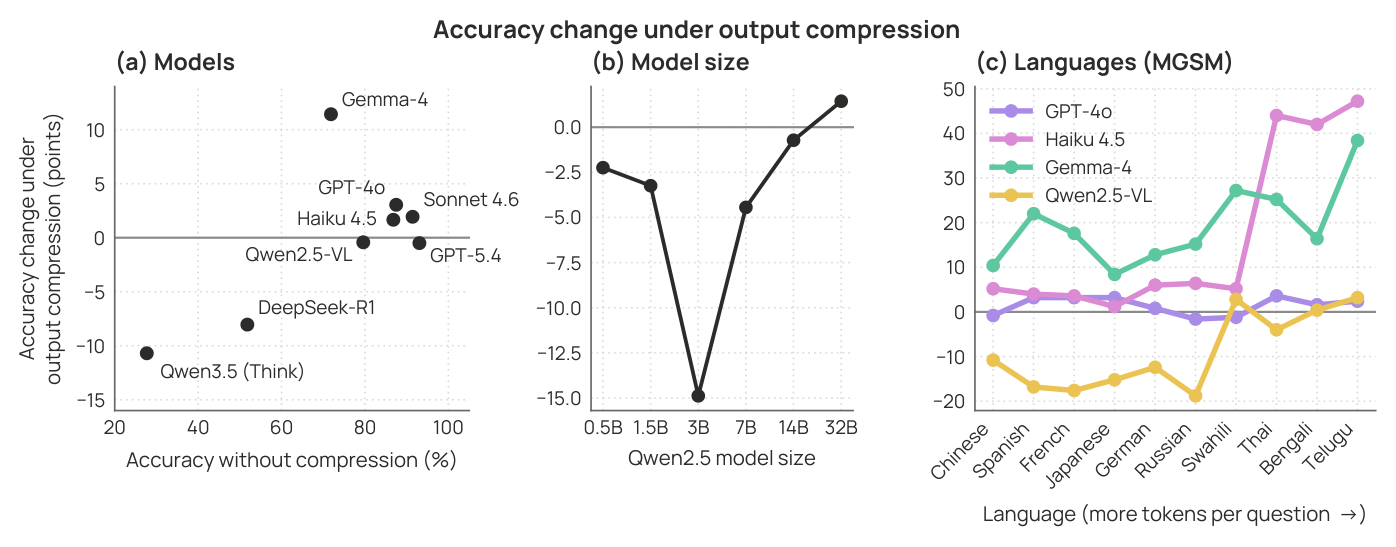
3. Which level works is specific to your model and your task. Gemma-4 gains 11.4 points under the same instruction that costs Qwen3.5-9B 10.7 points, and how strong a model is to begin with does not predict where it lands. So run the CAVEWOMAN framework on your own setup instead of copying a level out of our tables. The commands are above.

Accuracy change varies by model, size, and language
Accuracy change under the telegraphic constraint, by model, by model size, and by language.

Does this work in other settings?

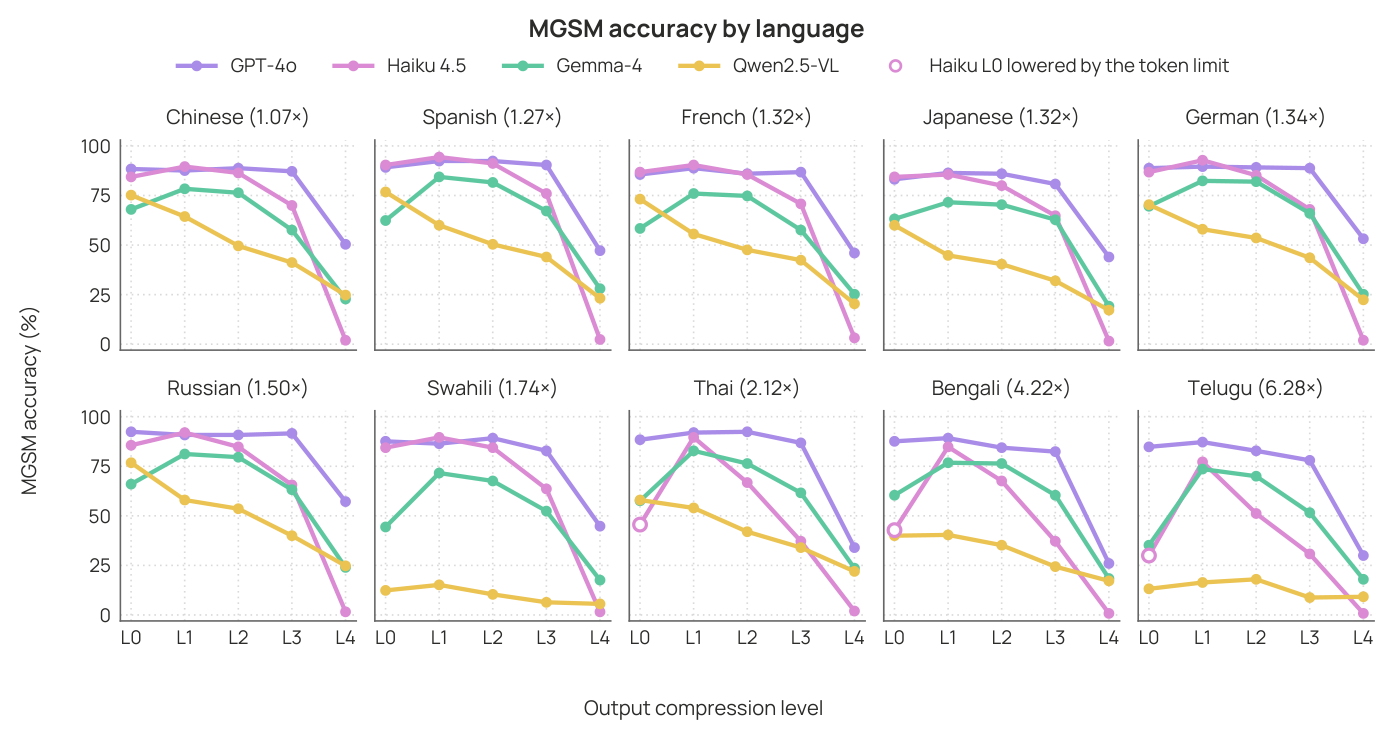
MGSM accuracy by language
MGSM in ten languages, ordered by how many tokens a question costs relative to English. The same constraint does not land the same way twice.

Does this only work for short questions in English? We checked four ways.

Multilingual MGSM in ten languages. Costs drop in every one. The English similarity checker does not work on non-English text, so there is a multilingual one you can switch to.
Long-form Summarizing news articles, where the answer is the text. Asking for a terser style does not reliably shorten it. Only L4, which sets a token count, does.
Size sweep Qwen2.5 from 0.5B to 32B. From 3B up, bigger models handle the instruction better. Below that it flips, because the smallest models start out so much worse that they have less to lose.
Thinking mode Qwen3 models write out their reasoning unless you turn it off with --disable_thinking. Leave it on and the reasoning eats the whole length budget, so every level looks the same.

Everything is compared against a baseline: the same question asked twice with nothing compressed. Compression has to move the answer more than that.

Full grid, 8 models x 5 benchmarks x 5 levels, both directions, plus every figure and the per-cell results: in the repo.

Conclusion

  • Compress the output, not the input.
  • Cheaper and correct does not mean unchanged. An answer can cost less, be right, and still not be what the model would have told you otherwise.
  • Every model lands somewhere different, so test on your own model and your own data.

Everything is released: the prompts, the per-cell results, and the scripts behind every table and figure. Start here, or clone github.com/danielle34/cavewoman.

Acknowledgements

We thank MIT Engaging for providing the GPU compute used to run the local-model sweep. We also acknowledge the maintainers of the open-source tools the work depends on, including spaCy, Hugging Face Transformers, and sentence-transformers.

This webpage template is adapted from Nerfies, under a CC BY-SA 4.0 License.

BibTeX

@misc{adeyemi2026cavewoman,
  title         = {CAVEWOMAN: How Large Language Models Behave Under
                   Linguistic Input and Output Compression},
  author        = {Adeyemi, Morayo Danielle and Rossi, Ryan A. and Dernoncourt, Franck},
  year          = {2026},
  eprint        = {2606.24083},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  url           = {https://arxiv.org/abs/2606.24083}
}